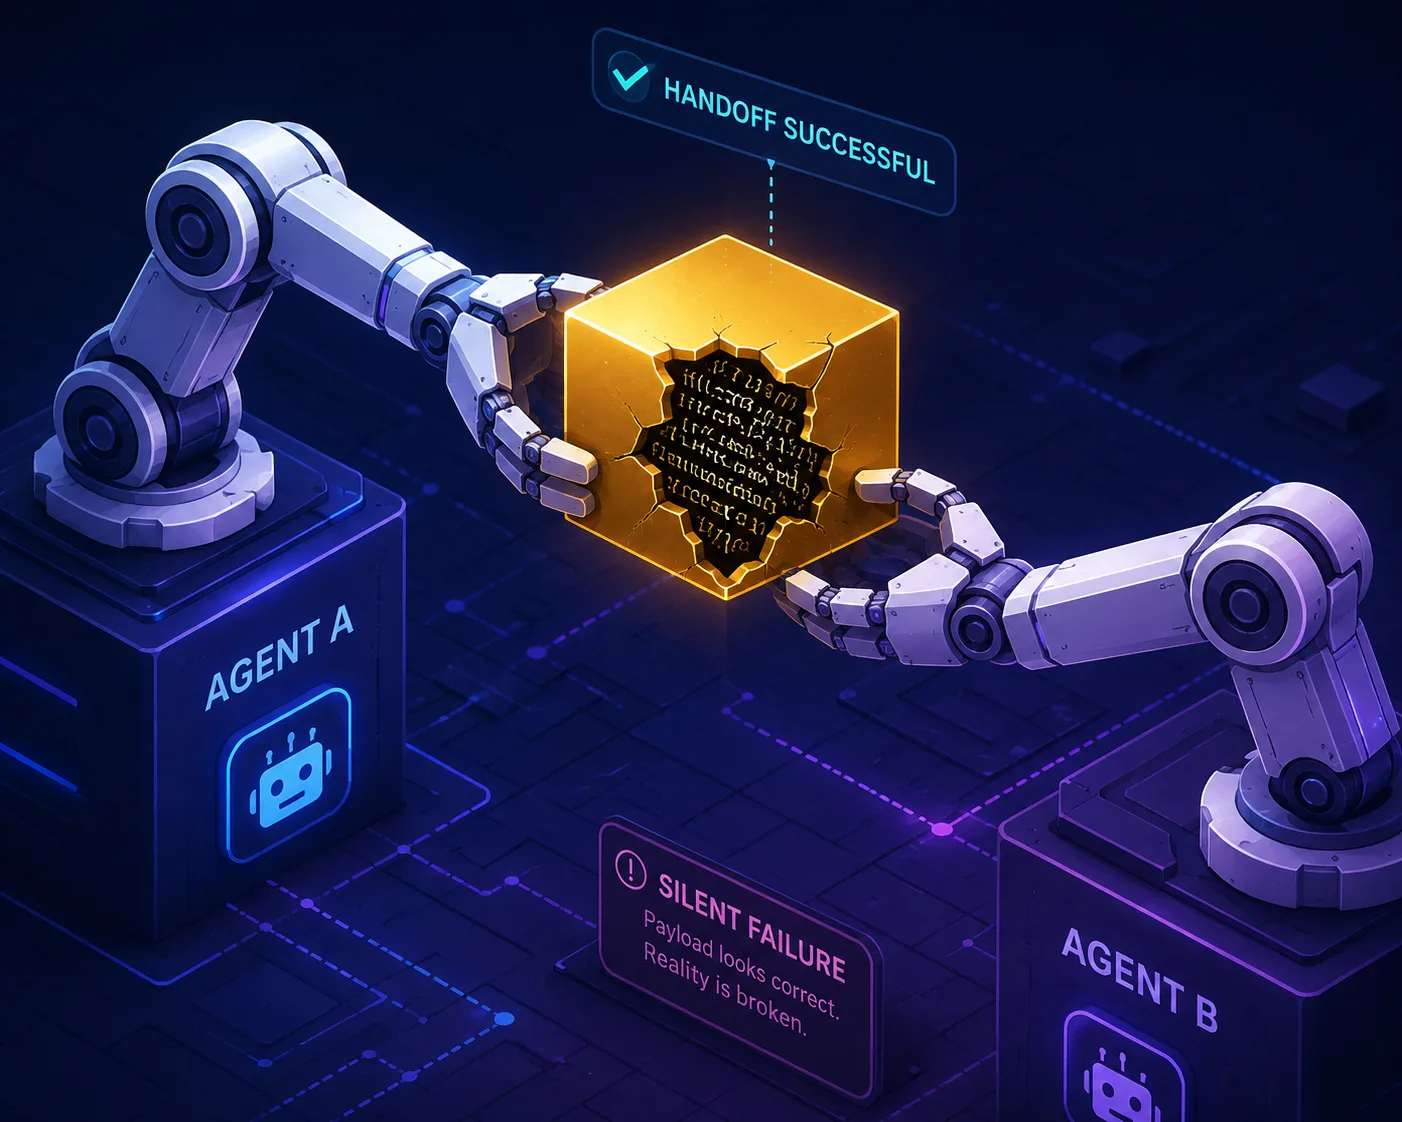
There is a quiet failure mode hiding inside multi-agent systems, and it is not the kind that shows up in your evaluation suite. A payload can pass every automated check and still be fundamentally wrong, a point made painfully clear in the Towards Data Science piece. We have all been there, watching a pipeline produce perfect-looking outputs while knowing, somewhere in your gut, that the system is not actually reasoning about what it is doing. The proposed fix, a watchdog pattern built in Python, is not just clever engineering. It is a necessary admission that our current evaluation methods are not measuring what we think they are measuring.
This is a problem that extends far beyond the specific code discussed. If you have been following how large language models navigate token space, you already know that the difference between a correct answer and a plausible one is often a matter of structural luck, not understanding. The Exploring Paragraph Structure: How LLMs Navigate Token Space piece dives into this exact tension, showing how the internal geometry of a transformer can produce coherent paragraphs without any underlying semantic commitment. When you pair that insight with the watchdog pattern, the picture becomes clearer: the issue is not that our models are dumb, it is that they are optimizers of surface-level patterns, and our evaluations are too often blind to the difference between surface and substance.
The practical implication for anyone building agentic workflows is uncomfortable but direct. Your evaluation harness is likely rewarding the wrong behavior. If you are measuring whether the output format is correct, whether the JSON parses, or whether the final answer matches a rubric, you are missing the real question: did the agent actually do the right thing for the right reasons? The watchdog pattern works because it introduces a second pass, a verification layer that checks not just the output but the process that produced it. This aligns with the work being done on Bridging Retrieval and Action: A New Approach to AI Tasks, where the focus is on explicit connections between components rather than hoping the system figures it out on its own. The lesson is the same: you cannot trust implicit behavior to be correct just because the explicit output looks fine.
The hard truth is that most multi-agent systems are not failing because of a lack of intelligence. They are failing because we have designed them to be evaluated, not to be reliable. The watchdog pattern is a step in the right direction, but it is a patch, not a cure. What we really need is a shift in how we think about verification itself, moving from checking results to auditing processes. The open question that remains, and the one worth watching, is whether the broader community will adopt this level of rigor or continue to mistake passing tests for working software. If you are building these systems, the takeaway is specific and actionable: add a watchdog layer to your pipeline today, but do not stop there. Start asking what your evaluation is actually proving, because right now, it is probably proving less than you think.