efficiency
Beyond Market Intelligence keeps efficiency in one place: 61 stories so far. The section currently leads with “Anthropic builds a team to design custom chips for faster AI models”, “Stop wasting hours on AI output that misses the mark”, and “Master reasoning budgets to make your AI work smarter, not harder”. Anthropic is assembling a team to design its own custom AI chips, a move that signals a deliberate shift toward co-designing hardware and models. Every hour spent untangling AI-generated filler is an hour you don't get back. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every efficiency story on Beyond Market Intelligence, newest first.

Anthropic builds a team to design custom chips for faster AI models
Anthropic is assembling a team to design its own custom AI chips, a move that signals a deliberate shift toward co-designing hardware and models. The Claude maker wants its technology to run faster and more efficiently, and that ambition starts at the silicon level. It's a smart bet on control and performance, even if the execution won't be simple. For anyone tracking how AI infrastructure evolves, this feels like a natural next step rather than a leap.
Stop wasting hours on AI output that misses the mark
Every hour spent untangling AI-generated filler is an hour you don't get back. This story calls out the real cost of sloppy outputs, and it's not just about wasted minutes. It's about the mental drag of cleaning up noise. We appreciate the push toward sharper, more intentional use of AI. For a deeper look at how AI can mislead even its creators, check out "Talking to My AI Clone Taught Me to Question the Tech." The fix starts with demanding better.

Master reasoning budgets to make your AI work smarter, not harder
Controlling how much an LLM thinks before it answers is quietly becoming one of the most practical levers in AI. This post breaks down reasoning effort and token budgets with the kind of clarity that makes you wonder why it took so long to ask. It's not about hype; it's about giving users a dial they can actually turn. If you're tired of guessing why some responses feel overthought or rushed, this is worth your attention.

When Multi-Agent Architecture Tripled Our LLM Costs and What Fixed It
A seemingly small shift to multi-agent architecture quietly tripled the token bill, and the author felt it in the ledger before the dashboard caught up. It's a sharp reminder that progress often hides its price tag. The fix wasn't a bigger budget but a smarter orchestration of prompts. If you're exploring AI's subtle costs, you might also appreciate "Talking to My AI Clone Taught Me to Question the Tech," which tackles hidden trade-offs from a different angle.

Streamline Your Coding Agent Workflow for Smarter Task Management
If you're juggling multiple coding agents, the chaos of scattered tasks can quickly become its own project. This guide cuts through the noise, offering a practical way to organize every request and keep your workflow moving. It's a straightforward approach for anyone tired of losing track of what each agent should be doing. For more on how AI handles structured work, our related piece on paragraph structure is worth a look.

Explore smarter data labeling by using AI to focus human effort where it matters most.
Human labeling is expensive, and most of it goes into teaching models what they should already learn from less. Using ML active learning to target annotation where it truly matters reduces paying for redundant work. It's a smart, grounded approach for teams feeling the squeeze on time and budget. If you're exploring smarter ways to train models, our guide on distributed algorithms pairs nicely with this mindset.
Let AI handle your most tedious recurring tasks and reclaim your time.
Most of us have that one task we dread, the recurring drain on our week. I handed mine to an AI agent, and it cleared 60% of it without breaking a sweat. That is not hype; it is relief. We are moving past building tools that merely assist, toward agents that actually own the work. If you are curious about where this hands-on autonomy leads, our related piece, "Bridging Retrieval and Action: A New Approach to AI Tasks," explores the mechanics behind the magic.

When Scaling AI Agents, Small CPU Tasks Become Big Bottlenecks
We scaled to hundreds of LLM agents and watched our system crawl. The culprit wasn't the models. It was the hidden cost of asynchronous design, where tiny CPU tasks quietly piled up until they became the bottleneck. This story is a practical look at that tradeoff, and it pairs well with our guide on distributed algorithms if you want the deeper mechanics. The takeaway is simple: more agents mean more overhead, and ignoring it slows everything down.

Monday.com sharpens its focus on AI with a leaner workforce
Monday.com is cutting 20% of its workforce, roughly 630 people, to double down on its AI Work Platform. That is a significant move, and it signals a clear priority: leaner operations in service of a more focused product vision. It is a bold bet on where the market is heading, and it reflects a willingness to make hard choices now rather than play catch-up later. For anyone tracking how AI is reshaping work, this is a story worth watching closely.

Discover how Microsoft positions its AI models for smarter, more cost-effective work.
Microsoft is reportedly coaching its salesforce to position its in-house AI models as the leaner, more cost-effective choice against OpenAI and Anthropic. That is a bold play, and an interesting one. It suggests the company believes efficiency will win over brand recognition in the enterprise market. We are watching a turf war over who owns the AI stack, and this move reframes the conversation from capability to cost.

Managing AI token budgets will become as routine as managing payroll.
Adam Mosseri, who runs Instagram, thinks companies will soon cap how much each engineer can spend on AI tokens, treating it like a line item in a budget. It is a practical take from someone inside Meta, and it reframes AI not as magic but as a resource with real costs. That is a shift worth watching. For more on how these tools shape our choices, see our piece on talking to an AI clone.
Smarter Traffic Management and Greater Efficiency with Linkerd 2.20
Linkerd 2.20 lands with sharper traffic management and meaningful efficiency gains, reinforcing why the CNCF-graduated service mesh remains a compelling lightweight choice for Kubernetes networking. The updates feel purposeful, targeting performance and observability without adding unnecessary complexity. For teams tired of wrestling with heavier meshes, this release invites a simpler path forward. If adaptive systems intrigue you, Mallika Rao's insights on real-world recommendations pair well with this momentum. Explore Linkerd's latest strides, and see how smarter routing can lighten your operational load.
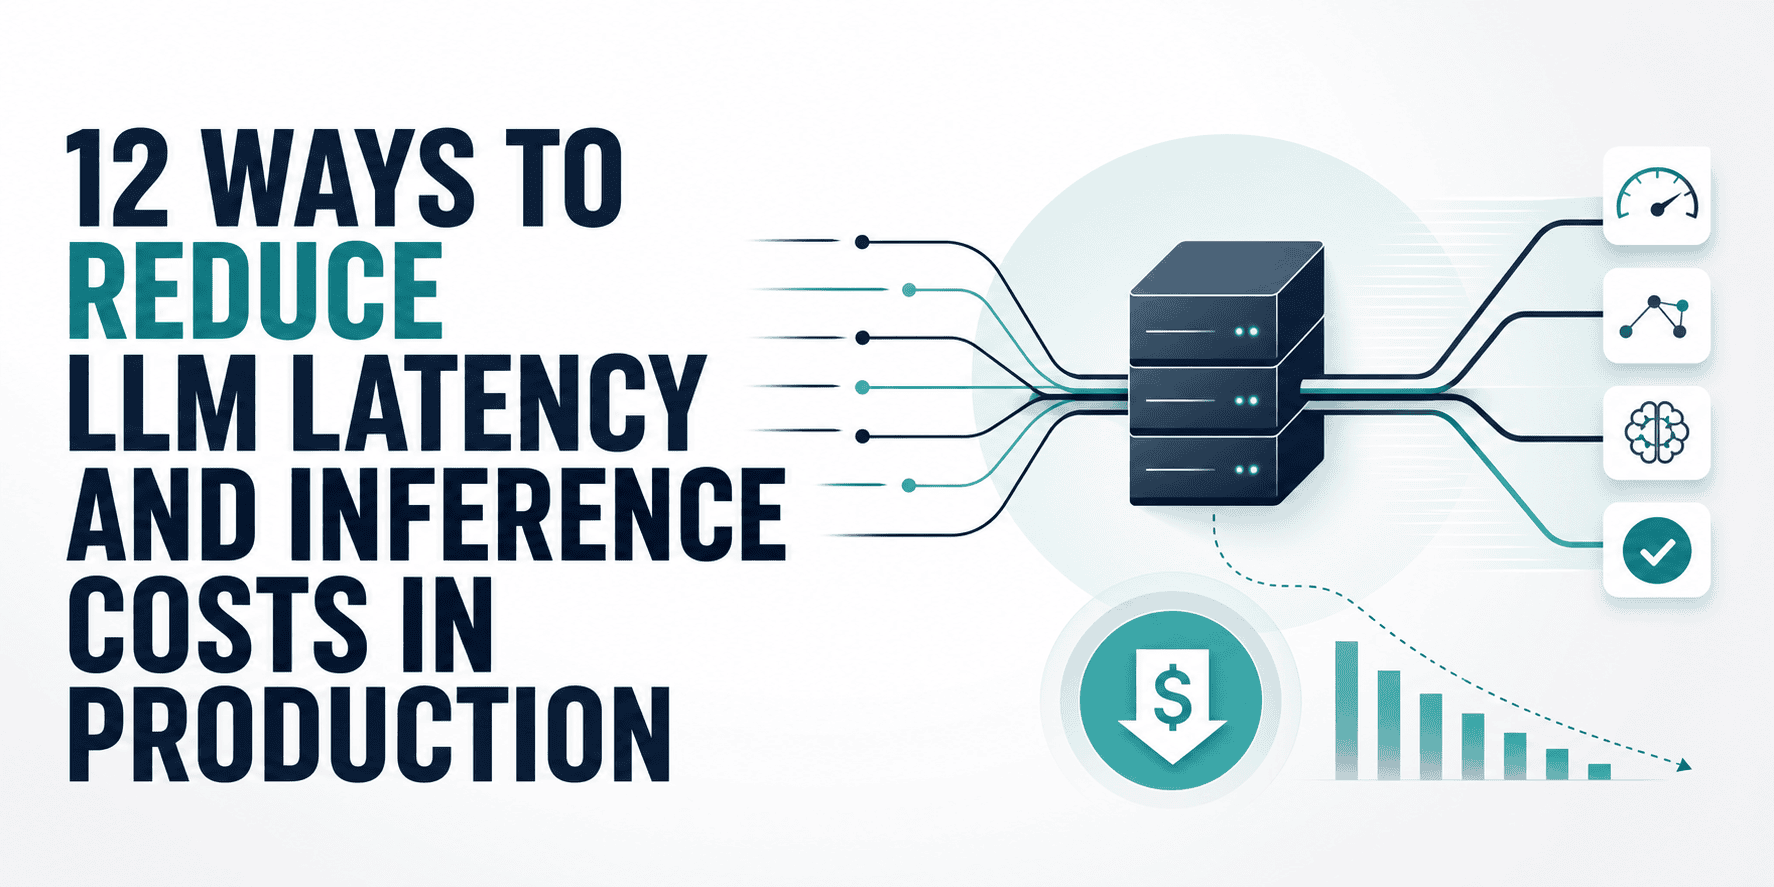
Stop Wasting Compute: Smarter Ways to Speed Up LLM Inference
Scaling LLMs isn't about adding GPUs. It's about removing wasted work from every request. That distinction shapes our latest guide, which lays out 12 practical ways to cut latency and inference costs without chasing hardware. Each tactic targets the inefficiencies that quietly slow production systems. If you're ready to move past brute-force scaling, this is where you start. For a deeper look at how distributed systems underpin these choices, our guide on unlocking distributed training algorithms pairs well with the conversation.