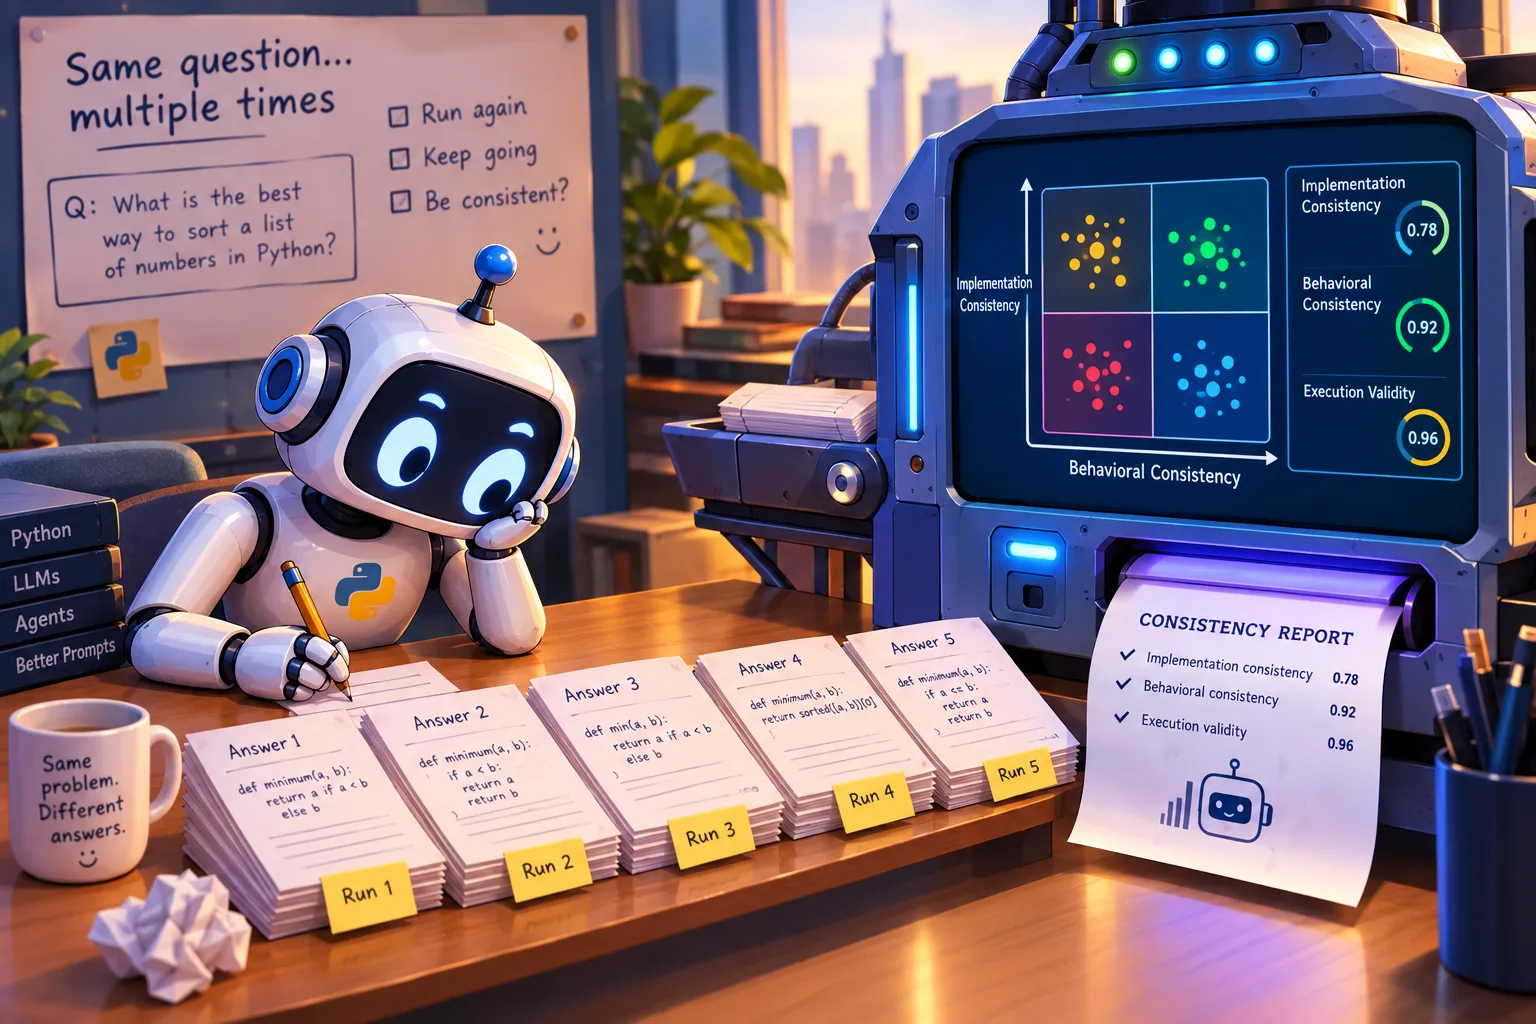
Most evaluations of coding agents lean on benchmarks that assume we already know the right answer. That assumption breaks down the moment you leave curated test sets and enter real-world codebases. The consistency quadrant approach flips the question: instead of asking whether an agent produces the correct output, it maps structural variance against execution results to estimate reliability without any ground truth. That is a genuinely useful reframing. It treats reliability as something you can observe through patterns of behavior, not as a score handed down from a labeled dataset. For teams evaluating AI tools, this is the difference between trusting a vendor's cherry-picked metrics and building your own evidence.
The practical implication is immediate. If you can group an agent's outputs into a quadrant based on how much their structure varies and whether they execute successfully, you get a diagnostic tool that works in your own environment, on your own code. High variance with consistent execution might suggest creative problem-solving. Low variance with broken outputs might reveal a model that is confidently repeating a flawed pattern. That distinction matters because it points to where you should intervene. Compare this to the challenge in When you shift marketing spend, does your MMM finally tell the truth?: a model can be internally coherent and still be wrong because the data it learned from never contained the necessary signal. The consistency quadrant faces a similar risk. An agent can be consistent and wrong. The method does not eliminate that possibility, but by separating structural consistency from execution success, it at least makes the failure mode visible.
There is also a useful parallel with the finding in A 1D physics solver wins, but neural networks take the lead in 5D. In that comparison, the value of a method depended heavily on the dimensionality of the problem. A simple solver dominated in one dimension, while neural networks pulled ahead in five. The consistency quadrant is similarly context-dependent. Its diagnostic power depends on how you define structural variance and what kinds of execution outputs you treat as meaningful. A team working on small, well-scoped functions may find the method straightforward. A team dealing with sprawling, interdependent services may struggle to map variance in ways that are actually informative. The framework is a lens, not a law.
The open question worth watching is whether this approach can be turned into a practical workflow rather than a post-hoc analysis. Measuring variance after the fact is useful, but the real value would come from using the quadrant in real time to decide when to trust an agent's output and when to request a second pass. That would move the conversation from reliability assessment to reliability enforcement. Until that happens, the consistency quadrant is a strong addition to the evaluator's toolkit, but it is not yet a replacement for judgment. The specific takeaway: when you evaluate your next coding agent, do not ask only whether it passed a benchmark. Ask how its outputs cluster and where the failures concentrate. That information will tell you more about deployability than any single accuracy number ever will.