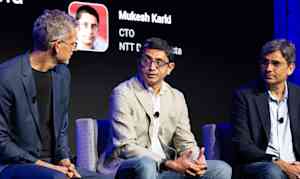
The numbers are hard to look away from, and not in a good way. Sixty-nine percent of enterprises are still running AI agents that share credentials, according to VentureBeat's own June research. That is a staggering vulnerability, especially when you consider the related incidents cropping up across the industry. It is a problem that feels urgent, yet the fix is not as simple as issuing new keys. As we have seen with recent incidents like AI Agents Shared User Images, Highlighting Data Security Concerns, the blast radius of poorly governed autonomy is very real. But as Mukesh Karki of NTT DATA AIVista and Mayank Upadhyay of Snowflake argued at VB Transform 2026, fixing identity is just the opening move in a much longer game. We agree, and we think the industry is only beginning to understand the depth of the challenge.
The core issue is that we keep applying human logic to a machine problem. Upadhyay makes a sharp point when he notes that traditional software is deterministic, but agents have a brain of their own. They rewire themselves. They explore. If you hand them a static API key that represents the union of everybody's needs, you are not managing access; you are building a disaster waiting for a trigger. The employee analogy helps us understand the intent, but it breaks down in practice. A star employee can learn the culture of a new company, but as Karki points out, you cannot realistically onboard and background-check 100 agents per employee. That is why we find the suggestion to treat agents like interns more compelling. Give them limited scope, keep an eye on them, and only expand their trust based on demonstrated behavior. It is a pragmatic middle ground, but it only works if the governance is layered directly into the action itself.
This is where the conversation moves beyond technical hygiene and into the realm of license to operate. Karki is right to say that provability is your license in a regulated environment. If you are in insurance, healthcare, or finance, an auditor is not going to accept a log that can be edited after the fact. They need tamper-resistant records that prove what an agent did, in the exact moment it did it. That means governance cannot be a wrapper you slap on after deployment. It has to sit outside the agent, at every action, built into the architecture from the ground up. Trying to retrofit this later is a fool's errand, especially when you are already scaling. The three-layer framework Upadhyay describes, agent, model, and data, is a solid mental model, but the practical takeaway for most teams is simpler: audit your static secrets first, and get visibility into shadow AI through an MCP gateway. Those are the two largest fixable attack vectors, and they are the ones causing the most pain right now.
What we would tell a reader who is staring down this problem is simple: do not wait for the perfect platform to arrive. Start with the assumption that every agent you deploy today is an intern who needs supervision. Scope its credentials tightly, but understand that scoped credentials are table stakes, not a finish line. The real question is whether you can prove what your agents did, after the fact, in a way that holds up in front of a regulator. If you cannot, you are not ready to scale. The watch item here is the tradeoff between constraint and capability. Karki and Upadhyay suggest task-level confidence scoring and sandboxing as a middle path, but the open question is whether enterprises will accept the operational friction of withholding autonomous execution on high-risk actions. The ones that do will build trust that lasts. The ones that do not will be the next cautionary tale, and we suspect they will not see it coming until the auditors come knocking.