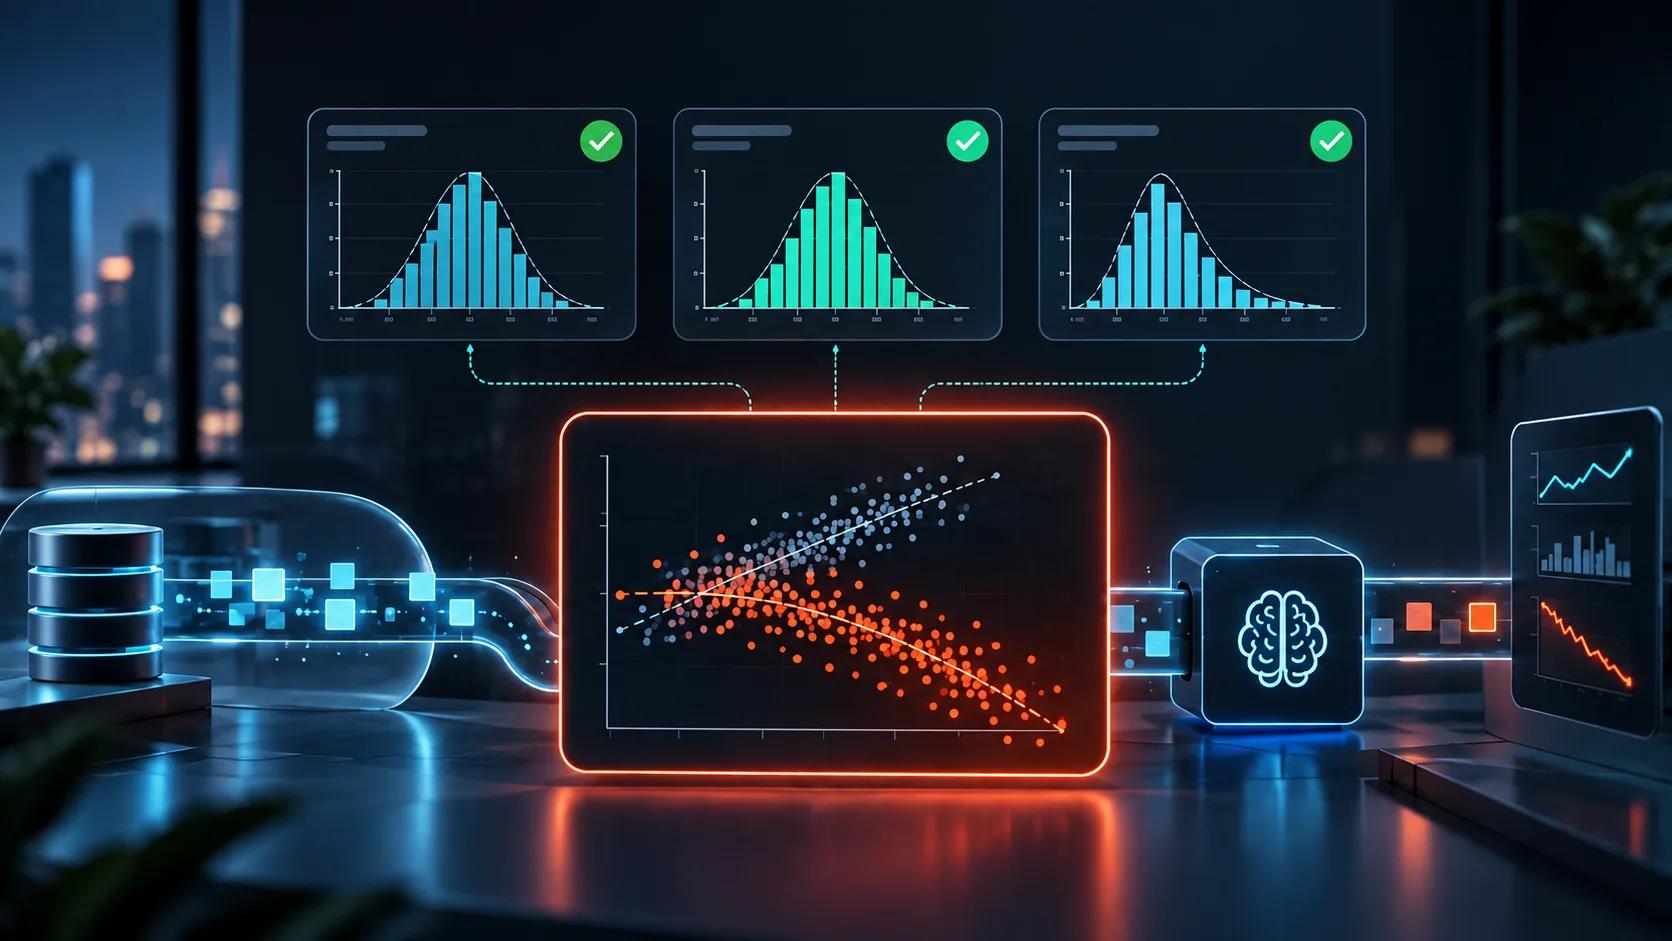
Data drift is one of those problems that feels straightforward until it isn't. Most teams know to monitor individual feature distributions, check the mean, check the variance, flag anything that moves. But as the recent article on adversarial validation shows, that approach can leave you blind to a subtler kind of decay: shifts in the relationships between features, even when each one looks perfectly stable on its own. The insight here is that your model isn't just a collection of independent inputs; it's a pattern of dependencies, and those dependencies can erode without a single alarm sounding. That matters because the cost of missed drift isn't just accuracy, it's trust in the entire pipeline.
What makes this technique worth your attention is its practicality. Adversarial validation, using scikit-learn, reframes the problem: instead of asking whether each feature has changed, you train a classifier to distinguish your training data from your production data. If the classifier can reliably tell them apart, drift is present, even if no individual feature looks suspicious. This is the kind of tool that turns a vague anxiety about model performance into an actionable signal. It connects directly to the challenge we explored in Clean Data Starts With Catching AI Slop Before It Skews Your Model, where early-stage data quality issues can silently corrupt outcomes. Here, the risk is later-stage, your model is live, and the world has shifted in ways your monitoring missed.
We would tell any reader managing production models to implement this as a routine check, not a forensic exercise. The barrier is low: a few lines of Python, a labeled dataset, and a binary classifier. The payoff is a second opinion on drift that your standard dashboards won't provide. It also forces a useful discipline: you must define what "normal" means for your training data, then systematically compare it to what arrives in production. That act alone surfaces assumptions you may have stopped questioning. And if you are building agents that act on their predictions, the stakes rise further. As Clean Architecture Removes the Signals Your Agent Needs points out, every abstraction layer you add can strip away the context your tooling relies on. Adversarial validation gives you one way to see through that noise.
The specific takeaway here is direct: if you are only monitoring univariate statistics, you are missing the drift that happens in the gaps between features. Start with a simple adversarial classifier on your next production batch. The result will either confirm your monitoring is sufficient or reveal a blind spot you did not know you had. The open question is how often you should run it, and whether your team is prepared to act when the answer is yes.