performance
performance at Beyond Market Intelligence is a file of 135 stories. The newest of them: “Exploring how one small edit can unravel a chess AI's deepest strategy”, “Explore how AI personalizes your creative workflow in the new Creator Studio app.”, and “One team's sprint proves what AI agents can achieve for your workflows.”. One head. Facebook's standalone Creator Studio app is here, and it brings an AI assistant straight into the creative workflow. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every performance story on Beyond Market Intelligence, newest first.

Exploring how one small edit can unravel a chess AI's deepest strategy
One head. Out of 128. Remove it, and a chess transformer stops seeing Morphy's legendary queen sacrifice entirely. That's the kind of surgical fragility worth pausing over, not because it breaks the model, but because it reveals how much meaning concentrates in a single parameter. The Chessformer Lens demo makes that visible, and the GitHub notebooks let you verify it yourself. For anyone curious about interpretability, this is a hands-on invitation to explore.

Explore how AI personalizes your creative workflow in the new Creator Studio app.
Facebook's standalone Creator Studio app is here, and it brings an AI assistant straight into the creative workflow. The tool studies your content style, performance, and audience engagement to offer personalized recommendations that actually match your goals. That's a practical step toward reducing guesswork, not a flashy gimmick. For creators juggling multiple formats, this feels like a thoughtful upgrade.
One team's sprint proves what AI agents can achieve for your workflows.
Three OpenAI engineers just shipped a million lines of code. That's not a headline; it's a starting point. For you, the real work begins with a ten-hour agent run. This story is about scale, but more importantly, it's about what happens when you stop wrestling spreadsheets and let AI handle the heavy lifting. We're not here to sell you hype, just a smarter way forward.
Enterprises invest in AI speed but lack visibility into infrastructure costs.
Enterprises are running AI in production, 66% have live workloads, and 29% operate at scale, yet fewer than half can rigorously track what that compute costs. Performance and GPU availability now outrank total cost of ownership, and reliability outranks price. That trade makes sense under pressure, but it leaves the weakest satisfaction score on value for money, a judgment made without full instrumentation. The next dollar targets specialized clouds and new silicon, even as current GPU utilization stalls near half.

Testing Local LLMs Against a 90-Tool Personal Assistant
Twenty-seven production tasks. Two local models. One hardware upgrade. That is the experiment at the heart of this piece, and the results are telling. The question is not whether local AI can match Claude feature-for-feature, but what it truly takes to replace the brain behind a 90-tool personal agent. The answer, unsurprisingly, is nuanced. For anyone questioning their own AI dependencies, this is a grounded, practical read.

Choosing the Right Python Tool for Your Data Workflow
Not all Python data libraries are created equal, and the choice between Polars and Pandas often comes down to what you're actually building. For AI developers, the question isn't just about speed; it's about matching the tool to the task. Pandas offers familiarity and a mature ecosystem, while Polars brings performance gains that can matter at scale. We think the answer isn't a simple switch, but a careful evaluation of your workflow.

Where AI learns the physics of teamwork and competition.
The Agentic World Cup asks a sharp question: what happens when LLMs stop crunching numbers and start playing soccer? The team behind it sees sports as the proving ground for embodied intelligence, a space where agents must react, adapt, and outmaneuver in real time. It's a clever reframing of the "embodiment gap," and the format is refreshingly direct: pick a model, coach it through prompts, and let it compete.
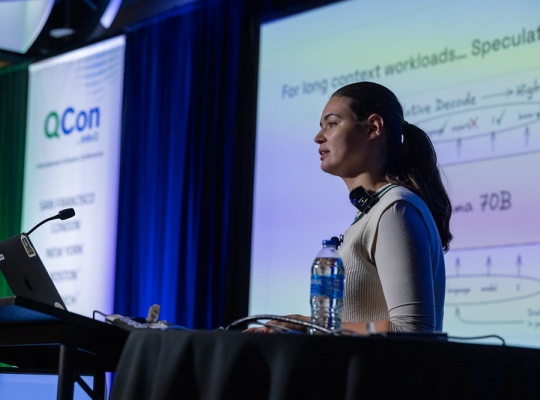
Designing Smarter Inference for High-Volume Workloads at Lower Cost
Meryem Arik's guide cuts straight to a question most teams avoid: how do you make AI inference genuinely cheap when the workload is massive but patience is on your side? Her answer isn't a single trick but a series of deliberate trade-offs across hardware, runtimes, and queue design. For engineering leaders tired of ballooning costs, her approach reframes non-real-time processing as a strategic advantage. It's practical, clear, and refreshingly grounded.
Discover how Fru brings faster random forest performance to Python and R users.
Building a faster random forest isn't just about squeezing out milliseconds; it's about unblocking bigger data work. That's what a colleague and I aimed for with Fru, a Rust-based implementation we just published in Software X. It offers bindings for Python and R, and the performance speaks for itself. In Python, Fru can outpace scikit-learn by several factors, and in some cases, it's hundreds of times faster.

Discovered Materials raises $9 million to find smarter materials for cooler chips
Discovered Materials just raised $9 million to play a high-stakes game of AI whack-a-mole, hunting for novel materials that could make chips cooler and more efficient. That's a smart bet, because the future of computing depends on finding the right elements, not just shrinking transistors. We like the focus on discovery over hype; it's practical, ambitious, and user-adjacent. For more on how AI shapes our tools, check out "Talking to My AI Clone Taught Me to Question the Tech."
When AI ships faster, performance demands smarter systems.
Shipping code faster creates a different kind of bottleneck. Martin Spier's talk on keeping ChatGPT fast reveals a truth many overlook: agentic workflows multiply change volume, and that pressure lands squarely on performance. It's not just about GPUs. The hidden costs of rapid deployment demand constant vigilance. Spier's approach, using always-on AI agents to automate profiling and regression detection, is a practical answer to a systemic problem. It's a smart, grounded strategy.

Stop optimizing speed and start reducing mental load in data work
Faster dataframe engines are a welcome upgrade, but they sidestep a deeper issue. The real bottleneck isn't speed; it's the sheer volume of syntax an analyst must hold in their head. pandas demands constant mental juggling, and no performance boost lightens that load. We should be designing tools that reduce cognitive friction, not just processing time. For a broader look at how we think about technical trade-offs, our piece on the Forrester function offers a useful parallel.

Anthropic builds a team to design custom chips for faster AI models
Anthropic is assembling a team to design its own custom AI chips, a move that signals a deliberate shift toward co-designing hardware and models. The Claude maker wants its technology to run faster and more efficiently, and that ambition starts at the silicon level. It's a smart bet on control and performance, even if the execution won't be simple. For anyone tracking how AI infrastructure evolves, this feels like a natural next step rather than a leap.
Speed up your C interpreters with minimal code changes
JIT compilers are powerful, but retrofitting them into existing interpreters often feels like a monumental task. Laurence Tratt's presentation on yk, an open-source meta-tracing framework, challenges that assumption. He demonstrates how C-based language interpreters, like Lua and MicroPython, can be sped up automatically with minimal, non-invasive code changes. The focus on tracing loops and managing complex deoptimization is particularly compelling. It's a practical, grounded approach to a difficult problem.
Explore Visual Reasoning: A New Benchmark for AI Models.
Visual reasoning has always been the quiet barrier between pattern-matching and true understanding. When we saw the benchmark challenge posed by /u/moschles, it felt less like a test and more like a mirror. We're not just asking AI to identify objects; we're asking it to explain why a circle isn't a square. That distinction matters. For anyone who has wrestled with the limits of current models, this exploration offers a practical lens.

Master reasoning budgets to make your AI work smarter, not harder
Controlling how much an LLM thinks before it answers is quietly becoming one of the most practical levers in AI. This post breaks down reasoning effort and token budgets with the kind of clarity that makes you wonder why it took so long to ask. It's not about hype; it's about giving users a dial they can actually turn. If you're tired of guessing why some responses feel overthought or rushed, this is worth your attention.
Explore how career growth can thrive beyond the four-year job mark
Four years in, the work still fits, the PTO lands, and the industry feels stable. That should be enough, yet the urge to leave isn't about dissatisfaction, it's about the quiet fear of narrowing options. The callback rate proves competence, but it also hints at a trap: depth in one field can start to feel like a cage. The real question isn't whether to stay, but whether comfort is closing doors worth opening. Sometimes, exploring means questioning why you're looking in the first place.
WebAssembly on the JVM unlocks new potential for server-side innovation
WebAssembly is no longer just a browser story, and Andrea Peruffo is here to prove it. His discussion on the JVM traces the technology's journey from simple interpreters to the speed of JIT compilation, making server-side Wasm a practical option for real workloads. What stands out is the focus on production reality, from edge platforms to modular plugins, rather than abstract potential.
Rethink your AI strategy for real competitive advantage
Most teams race to build bigger models or chase flashier features, yet they overlook the real advantage: how they frame the problem itself. In this piece, we explore why competing on raw capability misses the point. Instead, focus on what your data actually needs, not what the hype demands. It's a practical reframe. If you're questioning how deeply to trust AI outputs, our piece on verifying your AI's understanding offers a timely companion. The path forward is simpler than the noise suggests.

Discover how a simpler AI model can empower your data workflows
ChatGPT 5.6 is a dumber model, and I love it. There's a quiet confidence in choosing less cleverness when it means more clarity. For users tired of bloated features, this feels like a return to what matters: getting the job done without the noise. It's not about settling; it's about smart simplicity. If you're curious how AI can reshape everyday tools, our piece on verifying AI's understanding offers a practical starting point. Explore that, then see what a lighter touch can do for your workflow.

When Multi-Agent Architecture Tripled Our LLM Costs and What Fixed It
A seemingly small shift to multi-agent architecture quietly tripled the token bill, and the author felt it in the ledger before the dashboard caught up. It's a sharp reminder that progress often hides its price tag. The fix wasn't a bigger budget but a smarter orchestration of prompts. If you're exploring AI's subtle costs, you might also appreciate "Talking to My AI Clone Taught Me to Question the Tech," which tackles hidden trade-offs from a different angle.
Virtual Threads on JDK 25 Shift the Bottleneck to Your Code
JDK 24 didn't just tweak virtual threads; it moved the bottleneck. The monitor-related pinning that stalled Netflix on Java 21 is gone, but what replaces it demands more from you. Downstream-resource saturation now shifts the burden onto explicit bounding in your code. Sandeep Bharadwaj maps these failure modes with a practical sequence backed by a public benchmark. It's a grounded look at what production Java truly requires now. For a related angle on handling workload pressure, our piece on scaling sandboxes instantly pairs well here.
Simplify private network DNS management with Cloudflare's unified platform.
Managing internal DNS often means juggling separate systems for private and public traffic. Cloudflare just simplified that. Its Internal DNS service is now generally available, bringing authoritative and recursive DNS for private networks onto a single platform. That consolidation matters for teams tired of patching together fragmented tools. It is a practical step toward cleaner operations, not just another feature drop. For more on how Cloudflare approaches infrastructure efficiency, their work with EmDash shows a similar instinct for simplifying the backend.

The True Energy Cost of Running Local LLMs on Apple Silicon
Five models, sustained generation, and a wall-socket meter don't lie: running a local LLM on Apple Silicon has a real, measurable price. This piece puts actual wattage under scrutiny at $0.31/kWh, and the findings land with more weight than the RTX-3090 numbers hinted at. We appreciate the rigor here; it turns vague claims into a practical cost conversation. For those ready to move beyond basics, our guide to distributed algorithms offers a natural next step.